Skip to content
Ross King
[ Ross King ]Sheffield, UK
Available for full-time roles from Oct 2026

I work on AI evaluation and reliability.

MSc Artificial Intelligence candidate at the University of Sheffield. I build software for evaluating AI honestly: release gates for agents, benchmarks that can fail, and numbers you can trace back to the test that produced them. The same discipline runs through the data work — Spark-scale backfills, dbt warehouses and ML forecasts.

AI Evaluation & Reliability · ML Engineering · Data Engineering

projects shipped
tests across them
live demos

Hover or focus a figure for the source it is counted from.

Counted from the project registry, which gates every published number · 3 Aug 2026

Viewing as →
[ 01 ]

Three projects, shown working

/?lens=all · 3 of 10 shown

052026 · 5 min read

Agent Release Safety Gates

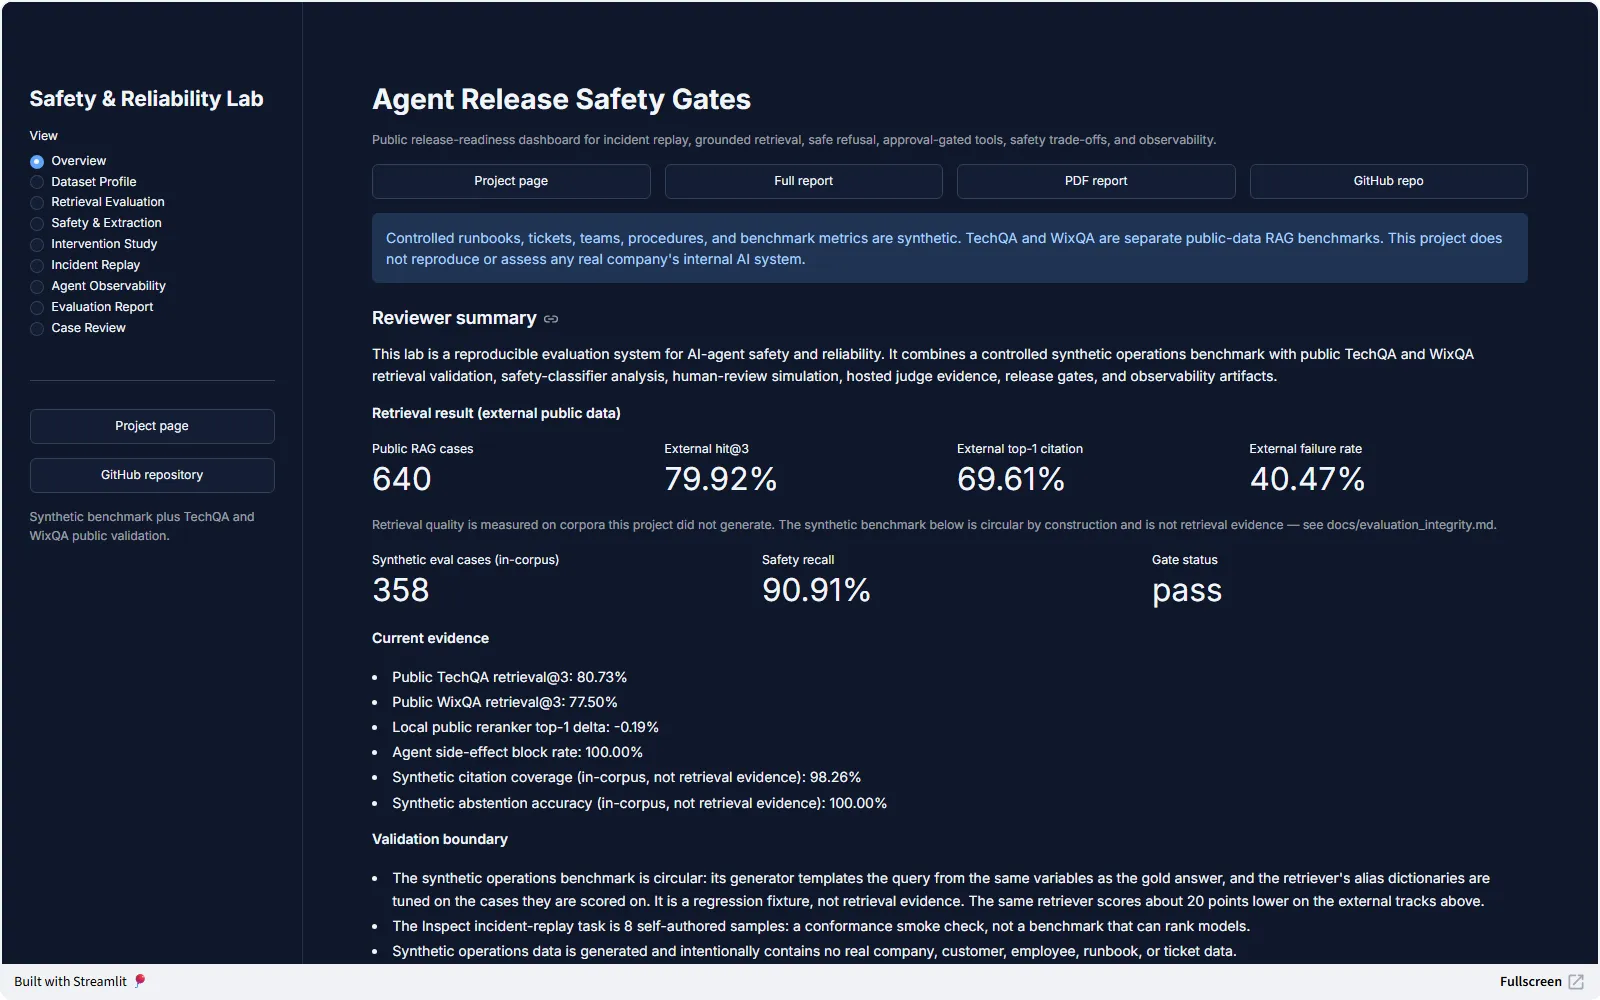
An installable release-gate for AI agents (pip install agent-release-gates): replay known incidents, apply policy-as-code gates, and produce ship / warn / block evidence — as a CLI that fails CI, a UK AISI Inspect eval, or a runner pointed at your own agent's traces. Its most useful result is a negative one: the project's own synthetic benchmark turned out to be circular by construction, and the same retriever scores about twenty points lower on 640 external public cases. The external number is the one reported.

Withdrawn: 99.31%. Corrected to 79.92% external retrieval hit@3.
PythonuvInspect AIPydantic
Read the write-up
agent-release-gates.streamlit.appLive
Screenshot of the Agent Release Safety Gates live demo
  • Project 06: redteam-foundry

    Python · Claude Sonnet 4.6 · Llama 3.1 8B · 4 min read

    0–4% measured against a control of 80% positive-control ASR
    attack success
    Controlled: a null result, carried by a positive controlRUN LOG

The rest of the bench

Not featured under this lens — the same rows, the same numbers. Open one for the short version.Compare all 10 on the index →

  • 02

    England & Wales Housing Decision Support

    dbt · DuckDB · Dagster · 3 min read

    7,264
    MSOAs scored
    Limits: a result published with its documented limitsLIVE
    uk-housing-decision-support.vercel.appLive
    Screenshot of the England & Wales Housing Decision Support live demo

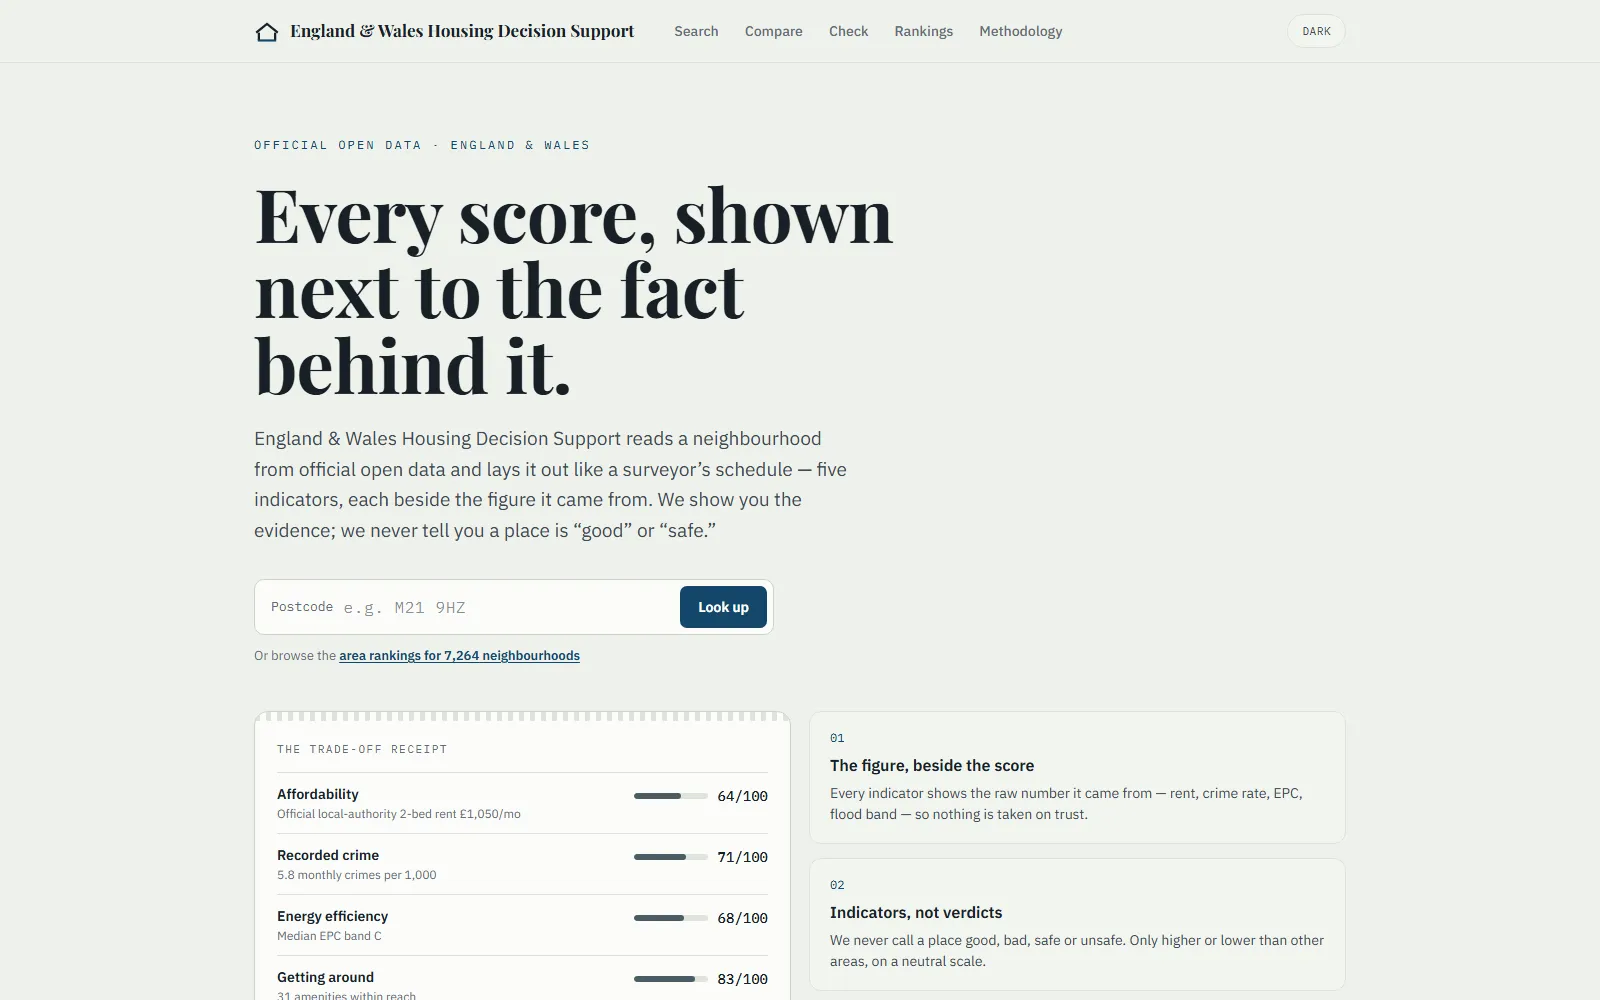
    Explainable where-to-live decision support for England & Wales. A tested dbt + DuckDB engine turns nine open-data sources into five transparent 0–100 indicators across 7,264 neighbourhoods, every score shown beside the raw figure it came from, served through a public FastAPI and a Next.js site with ~7k programmatic area pages. 228 dbt data tests + 2 unit tests, a versioned cross-runtime scoring contract, Dagster-orchestrated refresh, published lineage docs.

    dbtDuckDBDagsterFastAPI
    Read the write-up
  • 03

    Community Energy Flex

    Python · FastAPI · Pydantic · 3 min read

    15
    UK grid regions
    Limits: a result published with its documented limitsLIVE
    after-midnight-beta.vercel.appLive
    Screenshot of the Community Energy Flex live demo

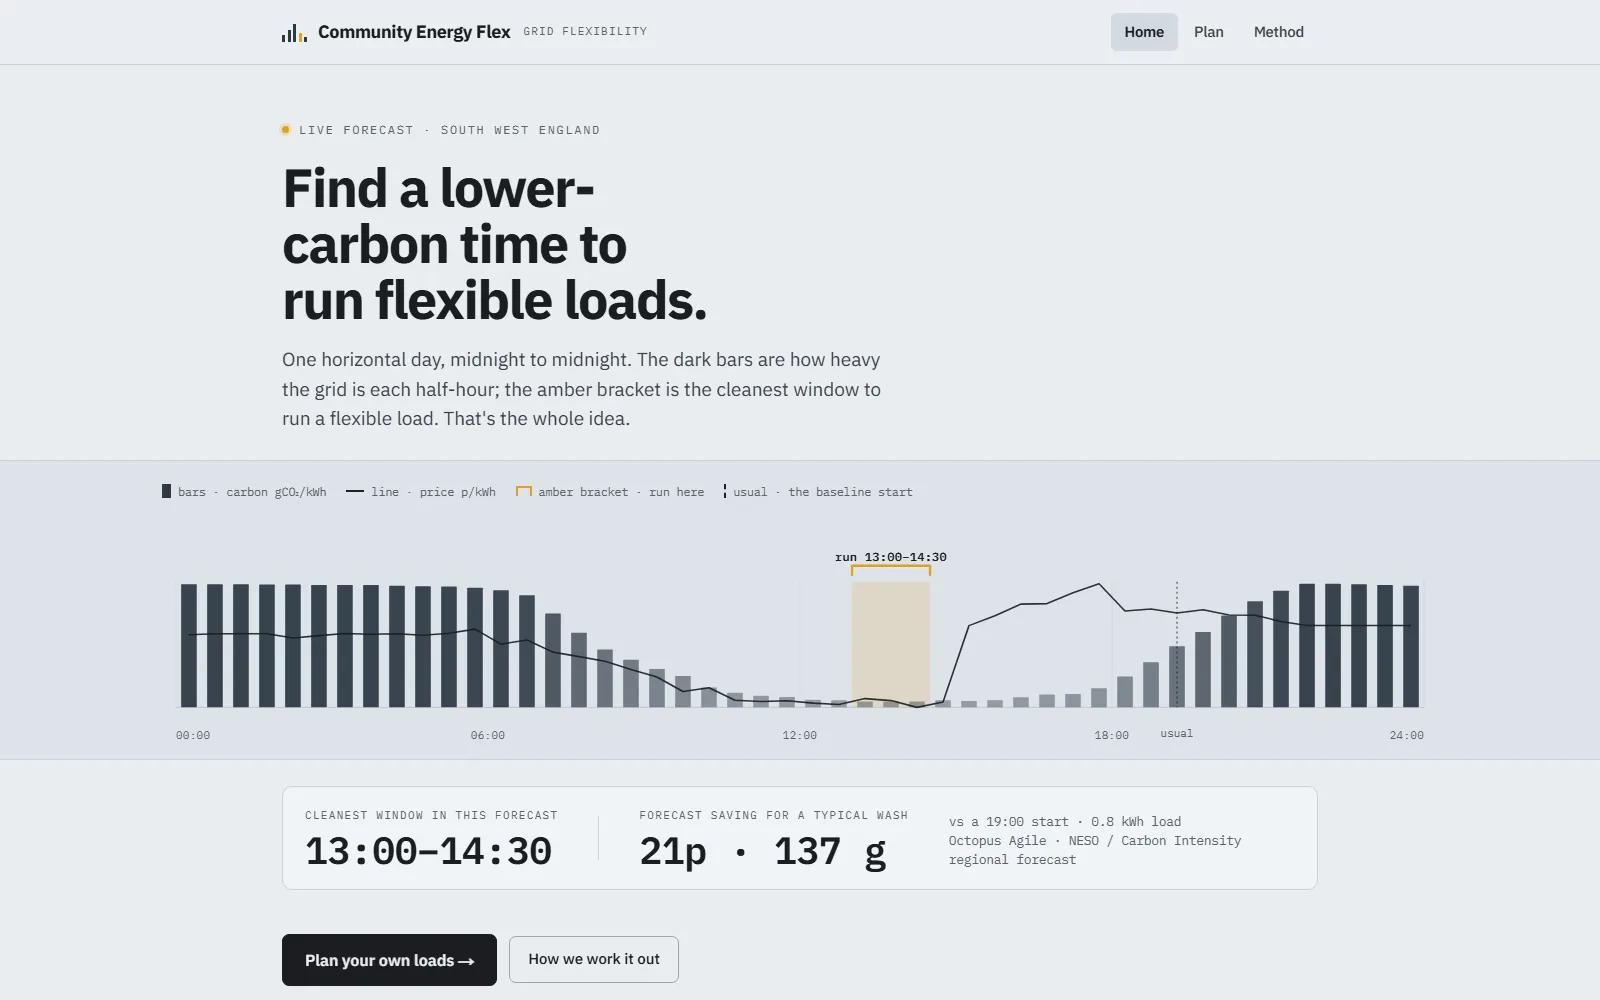
    Works out when to run flexible electricity loads — a wash, an EV charge — to cut cost and carbon from live UK grid data, and shows the working: an LP/MILP optimiser behind a typed FastAPI contract, a Next.js planner, and a scenario retro that re-scores a plan under alternative carbon curves. Product development stopped in July 2026 after a scan found the scheduling function already served by a statutory smart-tariff duty and three shipping products — recorded with its primary sources rather than quietly abandoned.

    PythonFastAPIPydanticNext.js
    Read the write-up
  • 04

    Aerospace Prognostics

    Python · FastAPI · Streamlit · 3 min read

    Withdrawn: 0.24. Corrected to 0.42 event-wise recall (corrected).
    Corrected: a published number was withdrawn and replacedRUN LOG
    run log
    Screenshot of the Aerospace Prognostics live demo

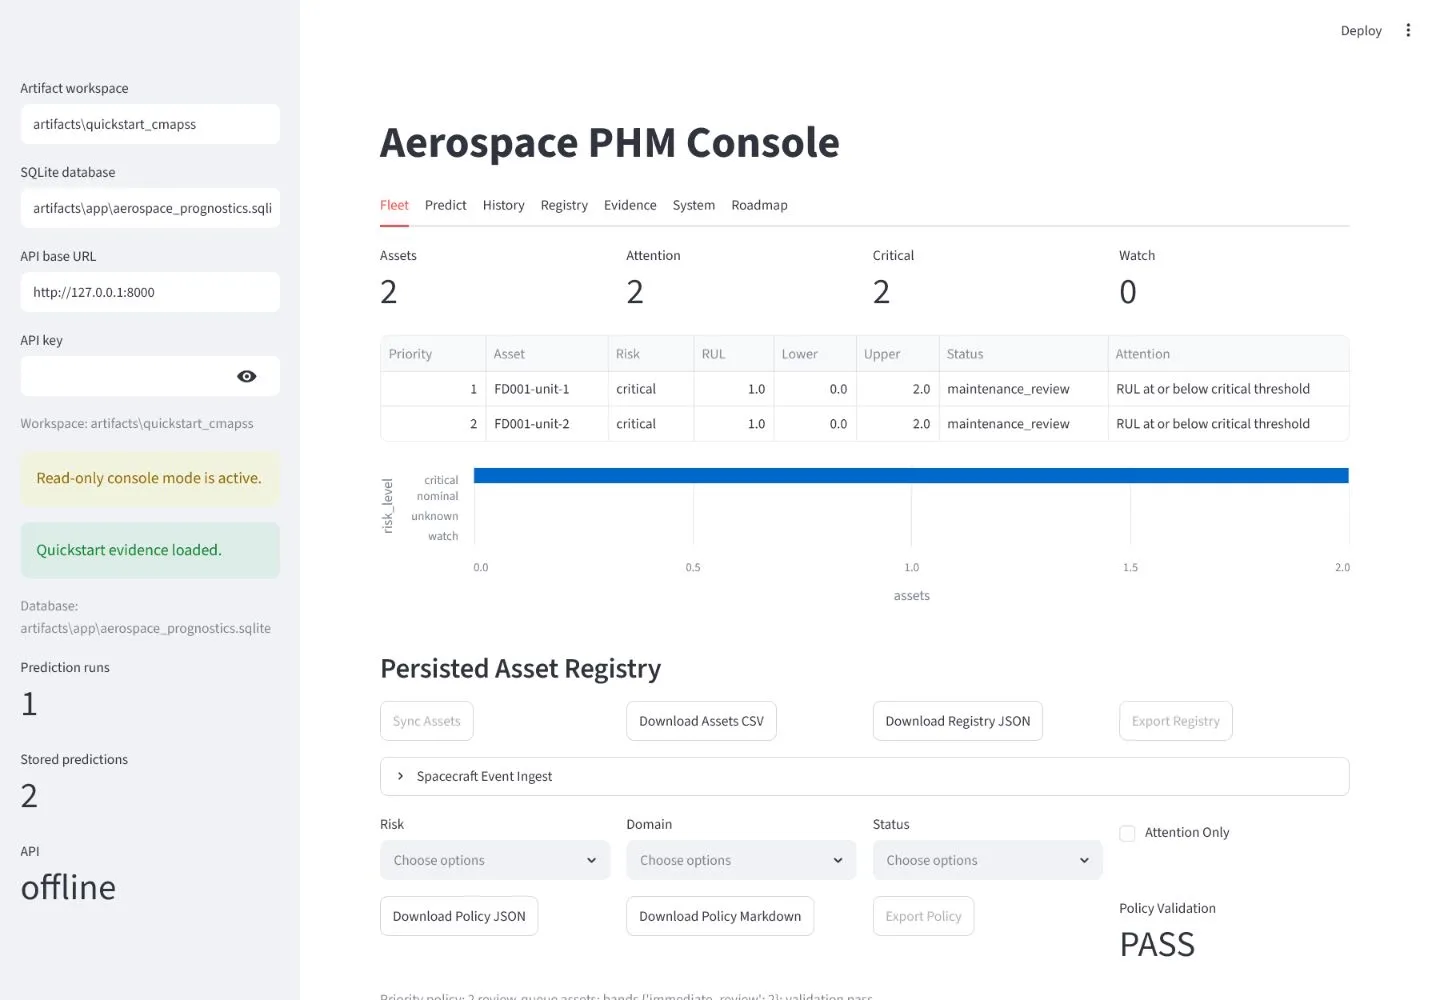
    Deployable end-to-end PHM MLOps, not another leaderboard notebook: NASA C-MAPSS turbofan RUL and ESA spacecraft-telemetry anomaly detection carried through their real evaluation protocols, wrapped in a FastAPI serving API, an operator console, signed release evidence (model card, SBOM, provenance), drift monitoring, and 462 tests. The evaluation layer proved general enough to extract as telemeval, a standalone library on PyPI with a Zenodo DOI.

    PythonFastAPIStreamlitDocker
    Read the write-up
  • 07

    Cited Market Brief Agent

    TypeScript · React · FastAPI · 3 min read

    Withdrawn: 1.000. Corrected to 0.400 holdout precision (corrected).
    Corrected: a published number was withdrawn and replacedLIVE
    cited-market-brief-agent.vercel.appLive
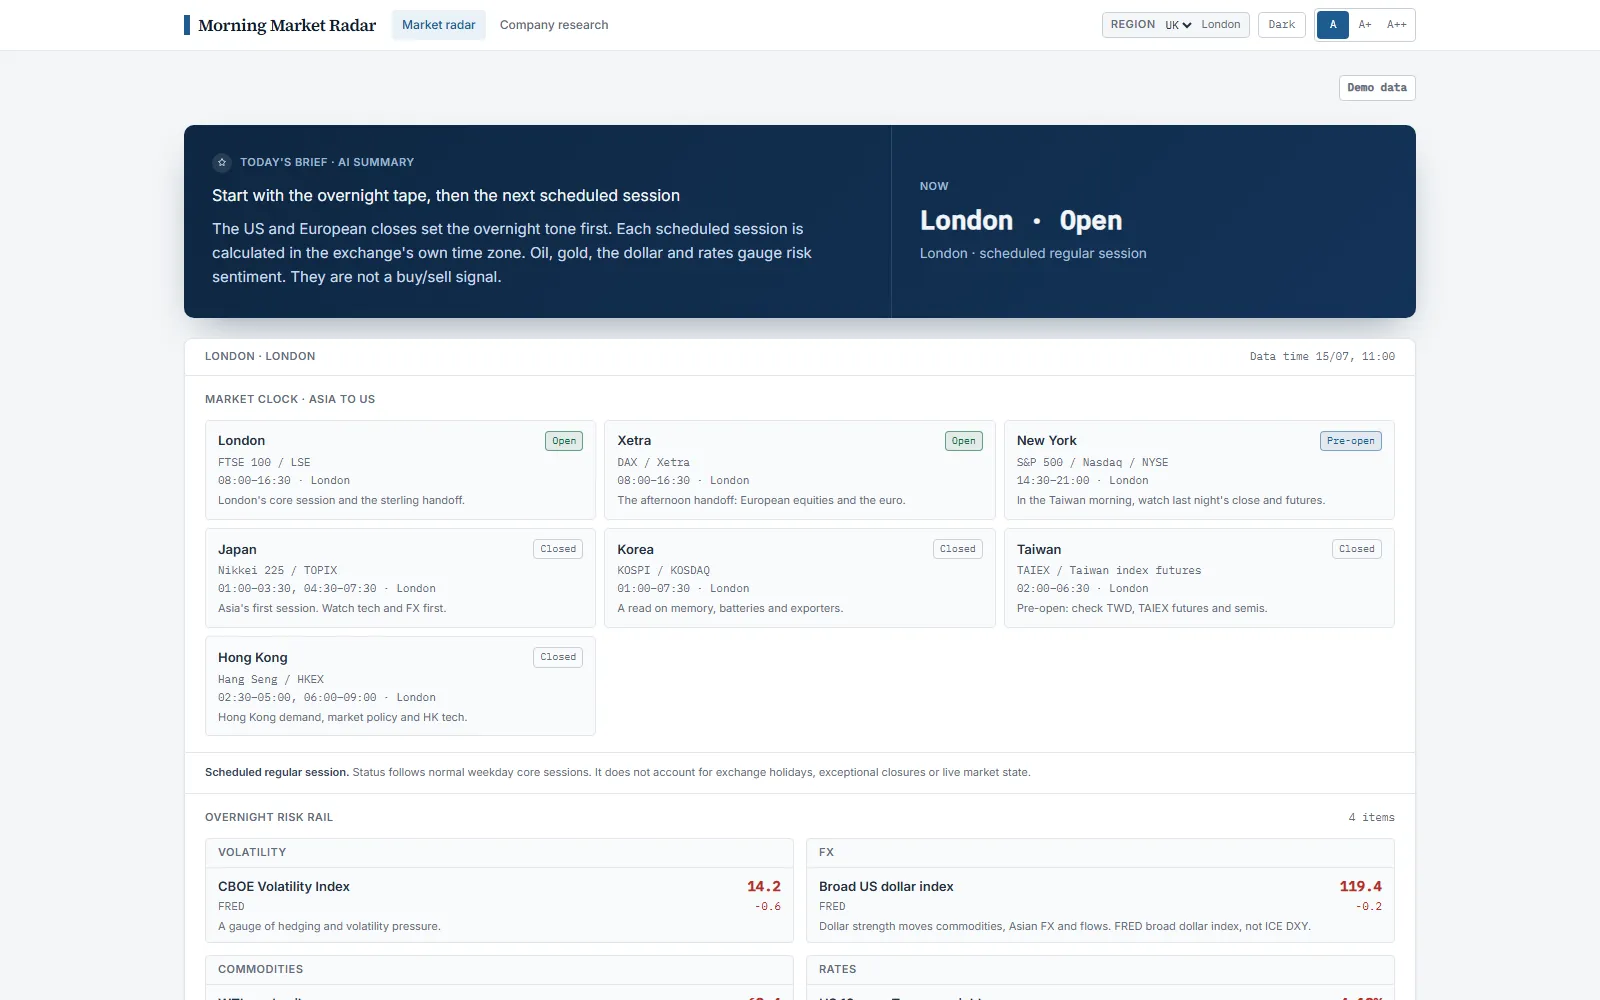
    Screenshot of the Cited Market Brief Agent live demo

    A region-aware morning-market web app and an audit-ready, evidence-backed brief engine in one. The radar surfaces a market clock, a FRED overnight-risk rail, most-read finance news with AI summaries, and a Taiwan ETF-vs-benchmark attribution tool; the brief engine generates company briefs from SEC EDGAR + FRED, attaching a stored source span to every claim it accepts, with a click-through evidence ledger. Four localised editions (Taiwan, Korea, UK, EU). The CI gate that once certified this at 100% turned out to be scoring itself; measured against independently labelled ground truth, 40% of accepted claims are genuinely supported by the span they cite.

    TypeScriptReactFastAPIPython
    Read the write-up
  • 08

    Responsible Neobank Growth

    Python · dbt · BigQuery · 3 min read

    217
    dbt tests (cloud run)
    Limits: a result published with its documented limitsLIVE
    responsible-neobank-growth.streamlit.appLive
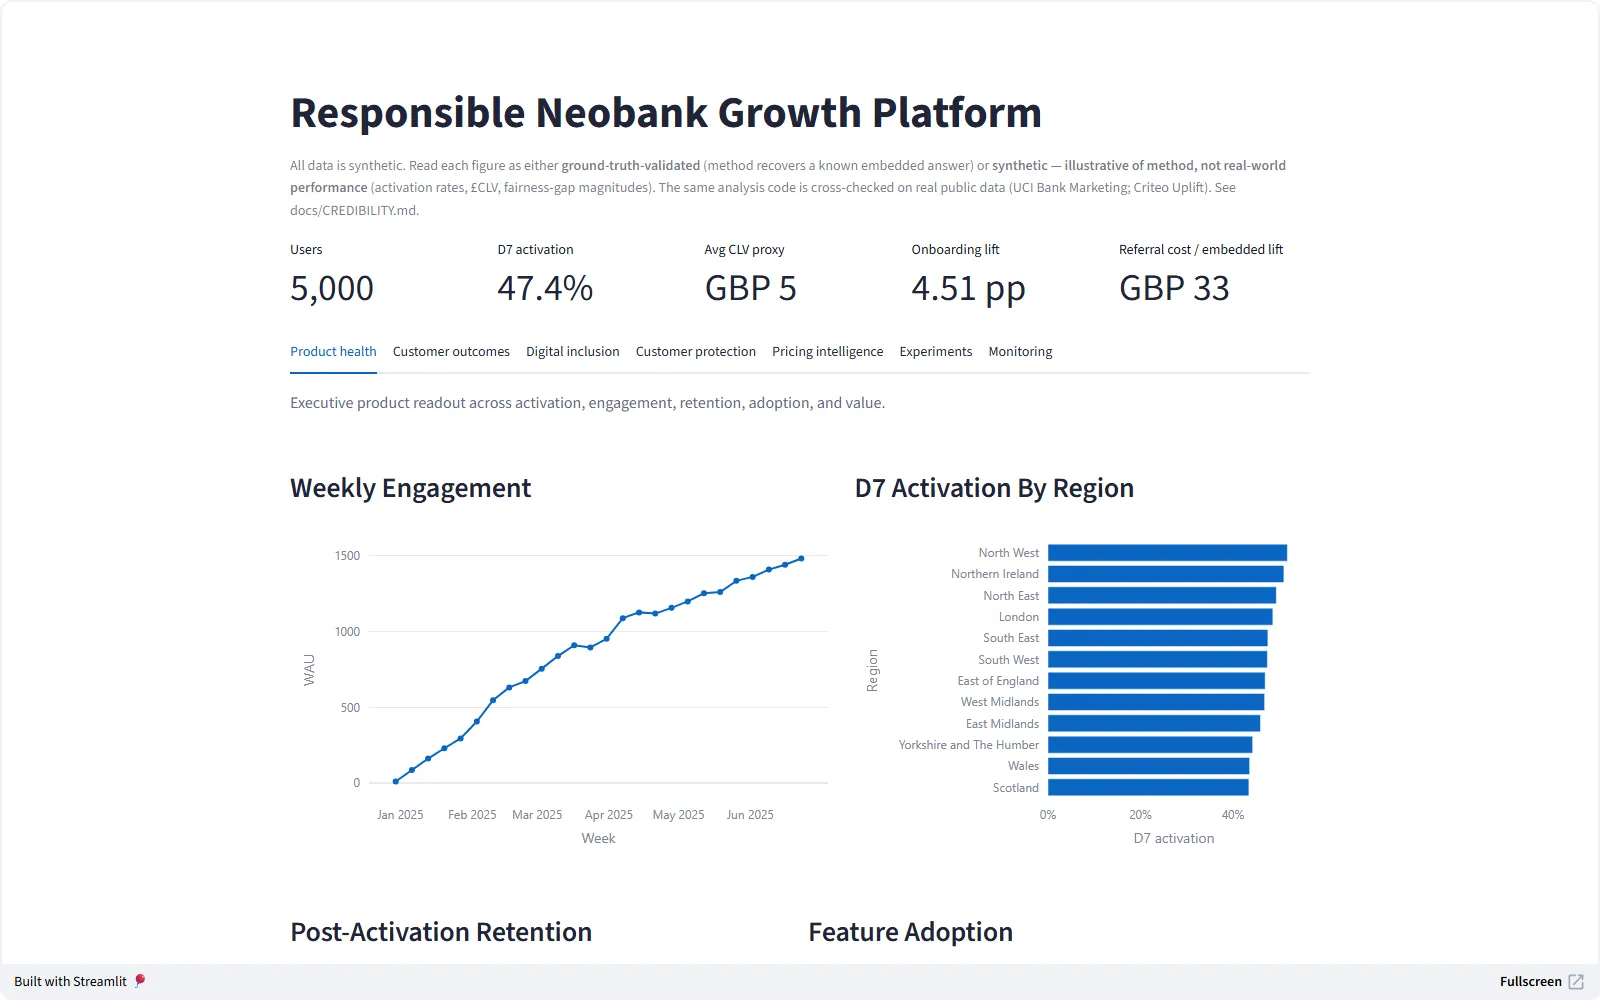
    Screenshot of the Responsible Neobank Growth live demo

    A synthetic neobank whose backend events misbehave on purpose — late, duplicated, reversed, schema-evolving — generated against a known-truth manifest so a governed dbt warehouse can be checked rather than trusted. On top sit the responsible-growth consumers: experimentation (CUPED, SRM, difference-in-differences, synthetic control), a calibrated activation model, and a release-gate that weighs customer-outcome guardrails. Run once on BigQuery: 68 dbt models under 217 data tests and 400 pytest tests, with full-refresh and incremental matching exactly at all six governed interfaces.

    PythondbtBigQueryDuckDB
    Read the write-up
  • 09

    Cashflow Risk Intelligence

    Python · FastAPI · PostgreSQL · 3 min read

    13-week
    runway forecast
    Limits: a result published with its documented limitsRUN LOG
    run log
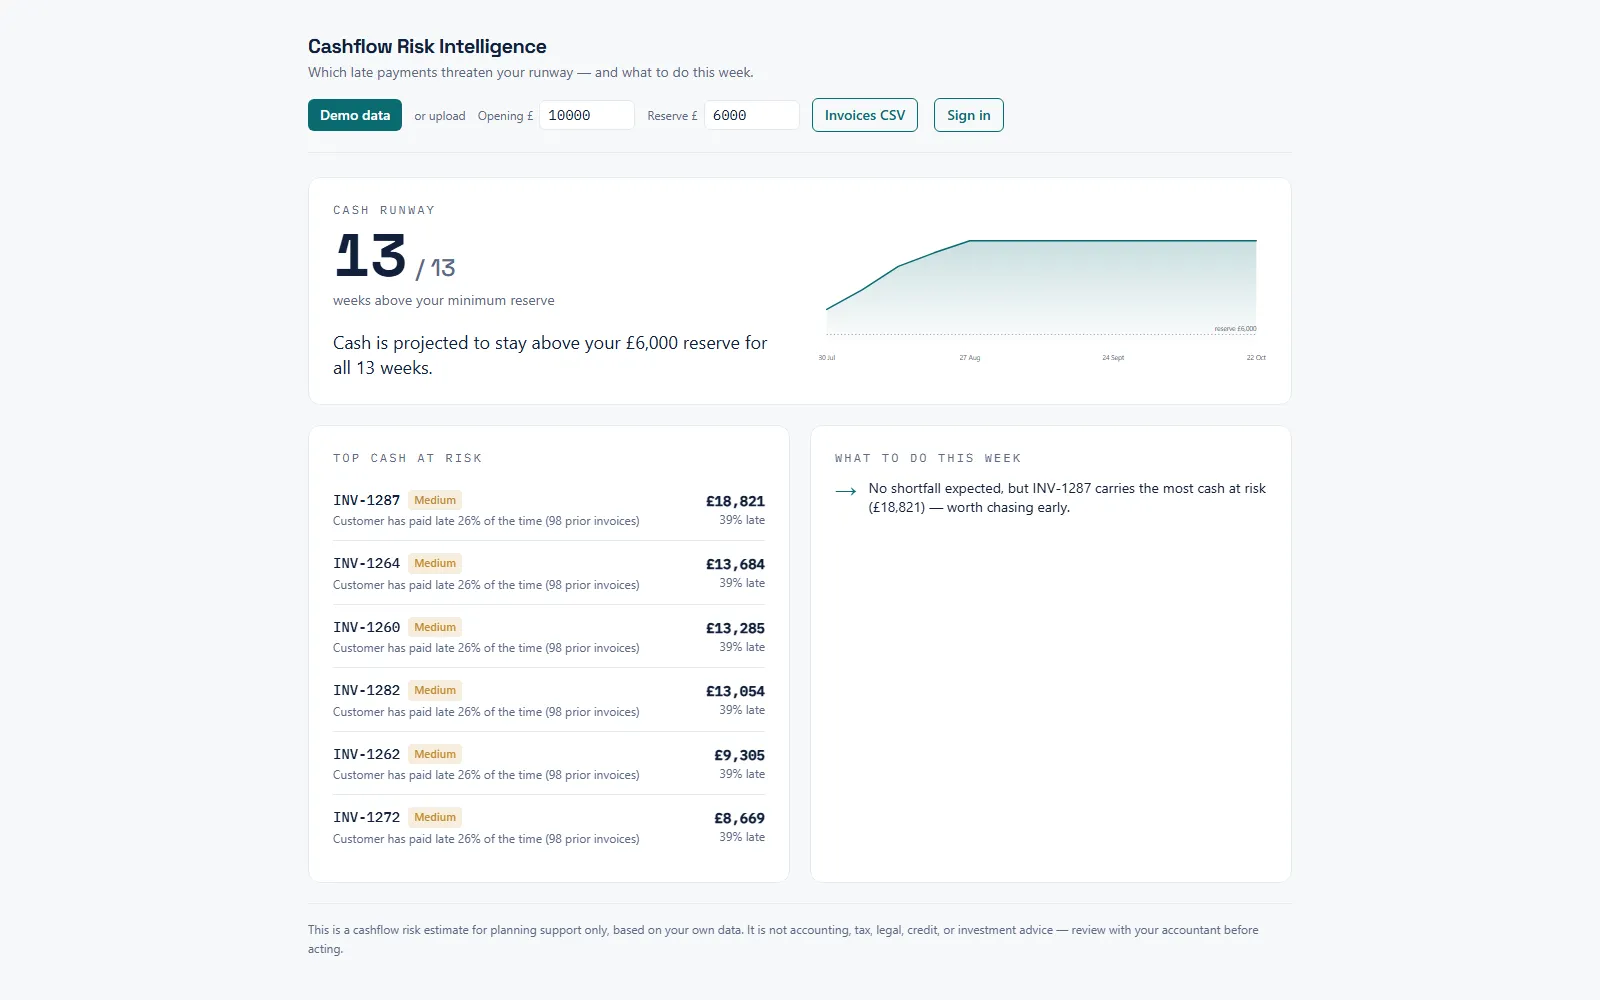
    Screenshot of the Cashflow Risk Intelligence live demo

    Which of a UK small business's unpaid invoices could break its cash runway, when the risk appears, and what to do this week: from an invoice CSV it forecasts a 13-week runway, ranks invoices by expected cash at risk with a plain-English reason on every score, enriches customer risk with Companies House filings, and writes the week's action brief — behind tested multi-tenant RBAC, a STRIDE threat model, and a DPIA.

    PythonFastAPIPostgreSQLNext.js
    Read the write-up
  • 10

    Marketing Effectiveness Lab

    Python · pandas · NumPy · 2 min read

    no metric published
    ARCHIVED
    rosscyking1115.github.io
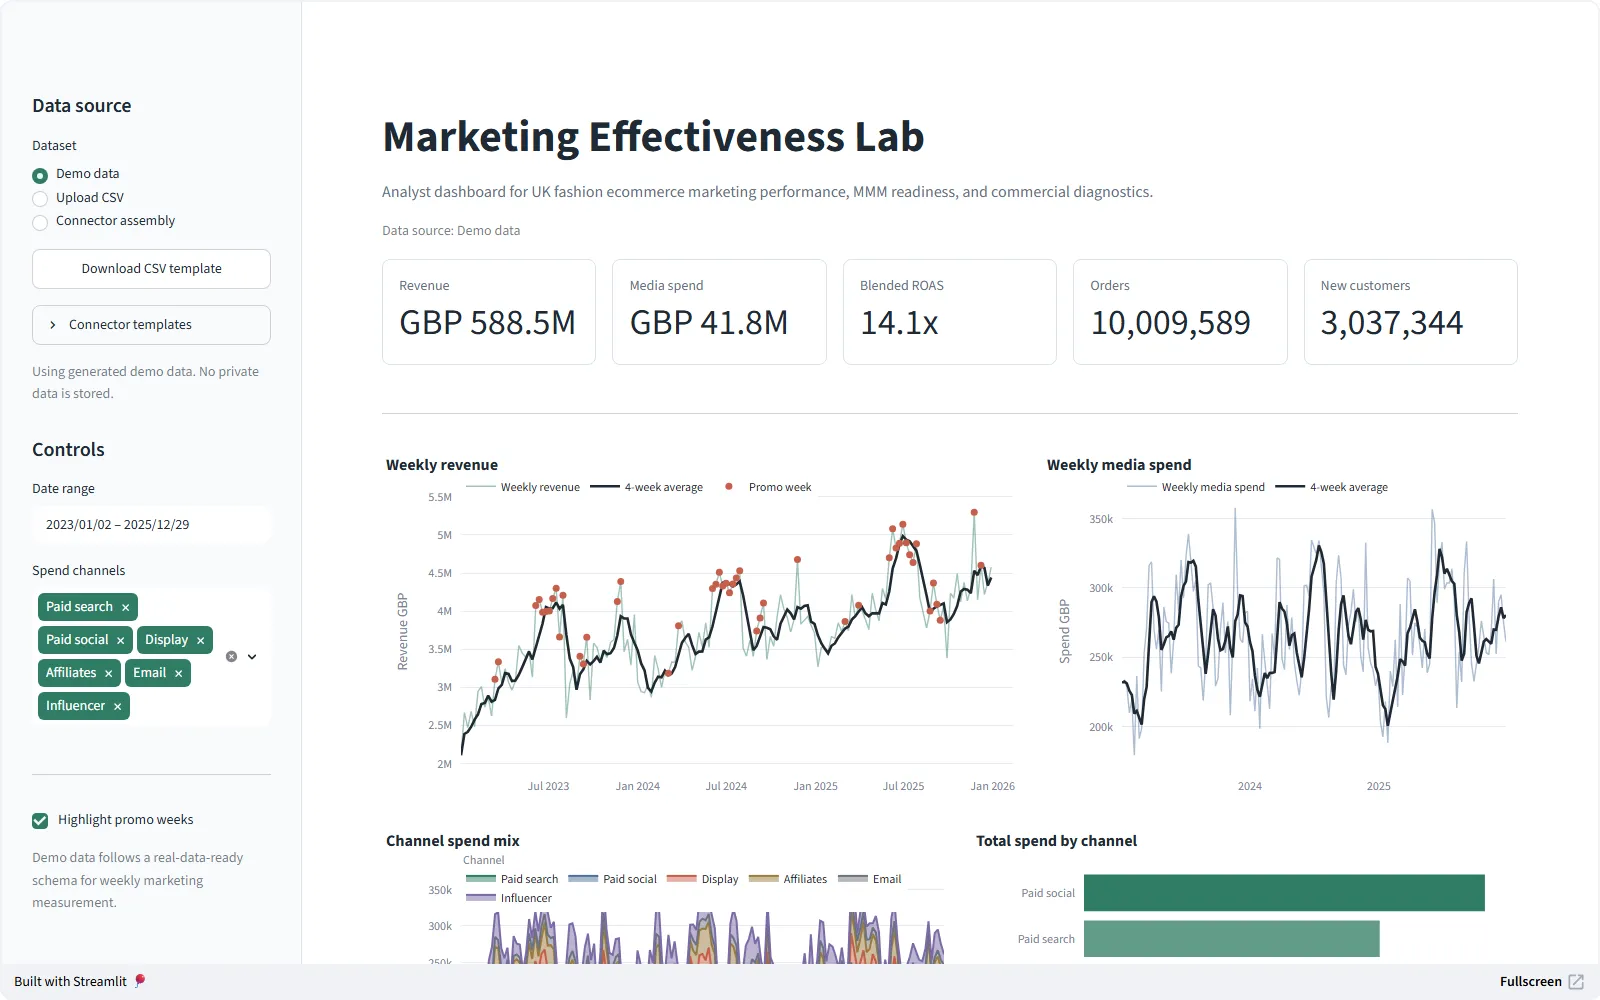
    Screenshot of the Marketing Effectiveness Lab live demo

    Helps a UK ecommerce team decide where next quarter's marketing budget actually drives incremental revenue — turning noisy multi-channel data into cautious, uncertainty-aware budget recommendations via marketing-mix modelling, a Bayesian posterior layer, lift-test calibration, and a constrained budget optimiser, with a Streamlit executive dashboard.

    PythonpandasNumPystatsmodels
    Read the write-up
[ 01 ]

Four projects, shown working

/?lens=ai · 4 of 10 shown

052026 · 5 min read

Agent Release Safety Gates

An installable release-gate for AI agents (pip install agent-release-gates): replay known incidents, apply policy-as-code gates, and produce ship / warn / block evidence — as a CLI that fails CI, a UK AISI Inspect eval, or a runner pointed at your own agent's traces. Its most useful result is a negative one: the project's own synthetic benchmark turned out to be circular by construction, and the same retriever scores about twenty points lower on 640 external public cases. The external number is the one reported.

Withdrawn: 99.31%. Corrected to 79.92% external retrieval hit@3.
PythonuvInspect AIPydantic
Read the write-up
agent-release-gates.streamlit.appLive
Screenshot of the Agent Release Safety Gates live demo
  • Project 07: Cited Market Brief Agent

    TypeScript · React · FastAPI · 3 min read

    Withdrawn: 1.000. Corrected to 0.400 holdout precision (corrected).
    Corrected: a published number was withdrawn and replacedLIVE
  • Project 04: Aerospace Prognostics

    Python · FastAPI · Streamlit · 3 min read

    Withdrawn: 0.24. Corrected to 0.42 event-wise recall (corrected).
    Corrected: a published number was withdrawn and replacedRUN LOG
  • Project 06: redteam-foundry

    Python · Claude Sonnet 4.6 · Llama 3.1 8B · 4 min read

    0–4% measured against a control of 80% positive-control ASR
    attack success
    Controlled: a null result, carried by a positive controlRUN LOG

The rest of the bench

Not featured under this lens — the same rows, the same numbers. Open one for the short version.Compare all 10 on the index →

  • 01

    London Cycle-Hire Analytics Platform

    Python · PySpark · dbt · 3 min read

    41.4M
    journeys unified
    Limits: a result published with its documented limitsLIVE
    tfl-data-engineering.streamlit.appLive
    Screenshot of the London Cycle-Hire Analytics Platform live demo

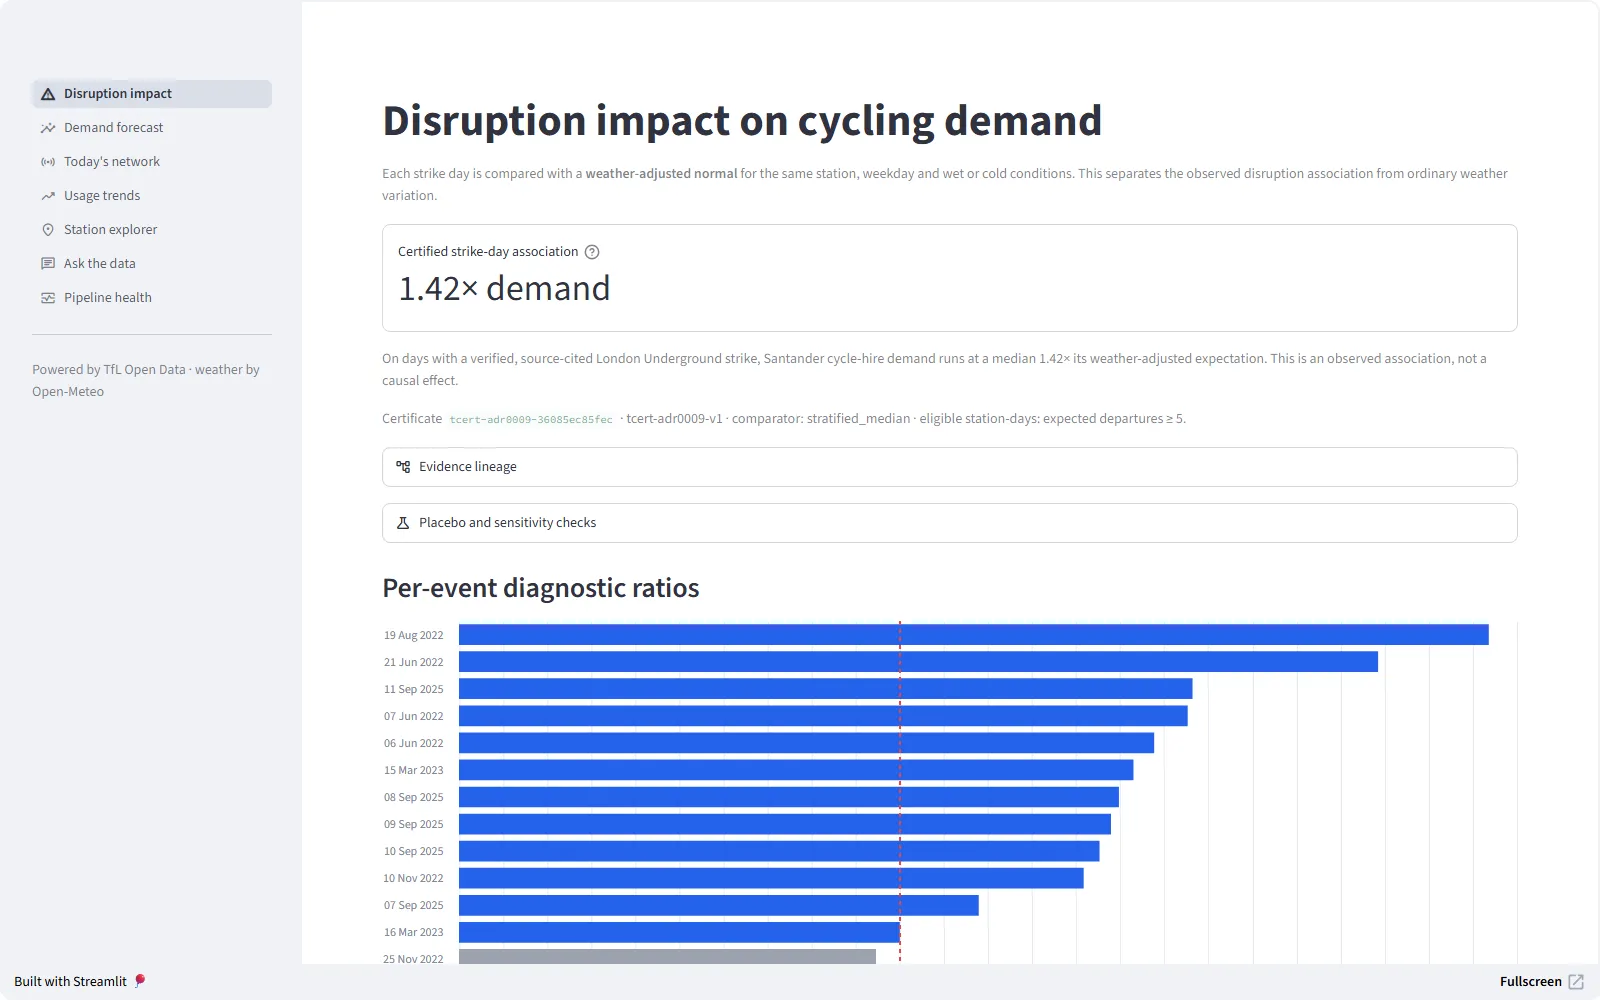
    Answers one question well: when London's transport is disrupted, how much extra demand lands on the bikes, and where? A 41.4M-journey PySpark backfill unified across five drifting schema eras, a tested dbt star schema, a LightGBM station-level forecast, and a free always-on live layer refreshed daily by GitHub Actions into committed Parquet — no warehouse to keep alive. Headline: strike days run about 1.4× median demand, up to ~2.3× on the worst full-network strike day.

    PythonPySparkdbtDuckDB
    Read the write-up
  • 02

    England & Wales Housing Decision Support

    dbt · DuckDB · Dagster · 3 min read

    7,264
    MSOAs scored
    Limits: a result published with its documented limitsLIVE
    uk-housing-decision-support.vercel.appLive
    Screenshot of the England & Wales Housing Decision Support live demo

    Explainable where-to-live decision support for England & Wales. A tested dbt + DuckDB engine turns nine open-data sources into five transparent 0–100 indicators across 7,264 neighbourhoods, every score shown beside the raw figure it came from, served through a public FastAPI and a Next.js site with ~7k programmatic area pages. 228 dbt data tests + 2 unit tests, a versioned cross-runtime scoring contract, Dagster-orchestrated refresh, published lineage docs.

    dbtDuckDBDagsterFastAPI
    Read the write-up
  • 03

    Community Energy Flex

    Python · FastAPI · Pydantic · 3 min read

    15
    UK grid regions
    Limits: a result published with its documented limitsLIVE
    after-midnight-beta.vercel.appLive
    Screenshot of the Community Energy Flex live demo

    Works out when to run flexible electricity loads — a wash, an EV charge — to cut cost and carbon from live UK grid data, and shows the working: an LP/MILP optimiser behind a typed FastAPI contract, a Next.js planner, and a scenario retro that re-scores a plan under alternative carbon curves. Product development stopped in July 2026 after a scan found the scheduling function already served by a statutory smart-tariff duty and three shipping products — recorded with its primary sources rather than quietly abandoned.

    PythonFastAPIPydanticNext.js
    Read the write-up
  • 08

    Responsible Neobank Growth

    Python · dbt · BigQuery · 3 min read

    217
    dbt tests (cloud run)
    Limits: a result published with its documented limitsLIVE
    responsible-neobank-growth.streamlit.appLive
    Screenshot of the Responsible Neobank Growth live demo

    A synthetic neobank whose backend events misbehave on purpose — late, duplicated, reversed, schema-evolving — generated against a known-truth manifest so a governed dbt warehouse can be checked rather than trusted. On top sit the responsible-growth consumers: experimentation (CUPED, SRM, difference-in-differences, synthetic control), a calibrated activation model, and a release-gate that weighs customer-outcome guardrails. Run once on BigQuery: 68 dbt models under 217 data tests and 400 pytest tests, with full-refresh and incremental matching exactly at all six governed interfaces.

    PythondbtBigQueryDuckDB
    Read the write-up
  • 09

    Cashflow Risk Intelligence

    Python · FastAPI · PostgreSQL · 3 min read

    13-week
    runway forecast
    Limits: a result published with its documented limitsRUN LOG
    run log
    Screenshot of the Cashflow Risk Intelligence live demo

    Which of a UK small business's unpaid invoices could break its cash runway, when the risk appears, and what to do this week: from an invoice CSV it forecasts a 13-week runway, ranks invoices by expected cash at risk with a plain-English reason on every score, enriches customer risk with Companies House filings, and writes the week's action brief — behind tested multi-tenant RBAC, a STRIDE threat model, and a DPIA.

    PythonFastAPIPostgreSQLNext.js
    Read the write-up
  • 10

    Marketing Effectiveness Lab

    Python · pandas · NumPy · 2 min read

    no metric published
    ARCHIVED
    rosscyking1115.github.io
    Screenshot of the Marketing Effectiveness Lab live demo

    Helps a UK ecommerce team decide where next quarter's marketing budget actually drives incremental revenue — turning noisy multi-channel data into cautious, uncertainty-aware budget recommendations via marketing-mix modelling, a Bayesian posterior layer, lift-test calibration, and a constrained budget optimiser, with a Streamlit executive dashboard.

    PythonpandasNumPystatsmodels
    Read the write-up
[ 01 ]

Three projects, shown working

/?lens=data · 3 of 10 shown

012026 · 3 min read

London Cycle-Hire Analytics Platform

Answers one question well: when London's transport is disrupted, how much extra demand lands on the bikes, and where? A 41.4M-journey PySpark backfill unified across five drifting schema eras, a tested dbt star schema, a LightGBM station-level forecast, and a free always-on live layer refreshed daily by GitHub Actions into committed Parquet — no warehouse to keep alive. Headline: strike days run about 1.4× median demand, up to ~2.3× on the worst full-network strike day.

41.4M
journeys unified
PythonPySparkdbtDuckDB
Read the write-up
tfl-data-engineering.streamlit.appLive
Screenshot of the London Cycle-Hire Analytics Platform live demo

The rest of the bench

Not featured under this lens — the same rows, the same numbers. Open one for the short version.Compare all 10 on the index →

  • 03

    Community Energy Flex

    Python · FastAPI · Pydantic · 3 min read

    15
    UK grid regions
    Limits: a result published with its documented limitsLIVE
    after-midnight-beta.vercel.appLive
    Screenshot of the Community Energy Flex live demo

    Works out when to run flexible electricity loads — a wash, an EV charge — to cut cost and carbon from live UK grid data, and shows the working: an LP/MILP optimiser behind a typed FastAPI contract, a Next.js planner, and a scenario retro that re-scores a plan under alternative carbon curves. Product development stopped in July 2026 after a scan found the scheduling function already served by a statutory smart-tariff duty and three shipping products — recorded with its primary sources rather than quietly abandoned.

    PythonFastAPIPydanticNext.js
    Read the write-up
  • 04

    Aerospace Prognostics

    Python · FastAPI · Streamlit · 3 min read

    Withdrawn: 0.24. Corrected to 0.42 event-wise recall (corrected).
    Corrected: a published number was withdrawn and replacedRUN LOG
    run log
    Screenshot of the Aerospace Prognostics live demo

    Deployable end-to-end PHM MLOps, not another leaderboard notebook: NASA C-MAPSS turbofan RUL and ESA spacecraft-telemetry anomaly detection carried through their real evaluation protocols, wrapped in a FastAPI serving API, an operator console, signed release evidence (model card, SBOM, provenance), drift monitoring, and 462 tests. The evaluation layer proved general enough to extract as telemeval, a standalone library on PyPI with a Zenodo DOI.

    PythonFastAPIStreamlitDocker
    Read the write-up
  • 05

    Agent Release Safety Gates

    Python · uv · Inspect AI · 5 min read

    Withdrawn: 99.31%. Corrected to 79.92% external retrieval hit@3.
    Corrected: a published number was withdrawn and replacedLIVE
    agent-release-gates.streamlit.appLive
    Screenshot of the Agent Release Safety Gates live demo

    An installable release-gate for AI agents (pip install agent-release-gates): replay known incidents, apply policy-as-code gates, and produce ship / warn / block evidence — as a CLI that fails CI, a UK AISI Inspect eval, or a runner pointed at your own agent's traces. Its most useful result is a negative one: the project's own synthetic benchmark turned out to be circular by construction, and the same retriever scores about twenty points lower on 640 external public cases. The external number is the one reported.

    PythonuvInspect AIPydantic
    Read the write-up
  • 06

    redteam-foundry

    Python · Claude Sonnet 4.6 · Llama 3.1 8B · 4 min read

    0–4% measured against a control of 80% positive-control ASR
    attack success
    Controlled: a null result, carried by a positive controlRUN LOG
    run log

    $ redteam-foundry run --matrix v1 # 12 cells: 2 models × 2 corpora

    » attack success: 0–4% across all 12 cells

    » positive control (llama2-uncensored): 80% [72, 87] — the pipeline can detect

    » cross-judge κ = +0.935 on the control; undefined in 11 of 12 cells

    » exports to a UK AISI Inspect eval log

    Adversarial benchmark foundry for LLM safety (pip install redteam-foundry): 1,883 prompts from four pinned corpora across 12 evaluation cells, with bootstrap confidence intervals and per-run API cost. Attack success came out at 0–4% — a negative result, so a known-vulnerable control model was pushed through the identical pipeline and scored 80%, which is what makes the zero mean something.

    PythonClaude Sonnet 4.6Llama 3.1 8BInspect AI
    Read the write-up
  • 07

    Cited Market Brief Agent

    TypeScript · React · FastAPI · 3 min read

    Withdrawn: 1.000. Corrected to 0.400 holdout precision (corrected).
    Corrected: a published number was withdrawn and replacedLIVE
    cited-market-brief-agent.vercel.appLive
    Screenshot of the Cited Market Brief Agent live demo

    A region-aware morning-market web app and an audit-ready, evidence-backed brief engine in one. The radar surfaces a market clock, a FRED overnight-risk rail, most-read finance news with AI summaries, and a Taiwan ETF-vs-benchmark attribution tool; the brief engine generates company briefs from SEC EDGAR + FRED, attaching a stored source span to every claim it accepts, with a click-through evidence ledger. Four localised editions (Taiwan, Korea, UK, EU). The CI gate that once certified this at 100% turned out to be scoring itself; measured against independently labelled ground truth, 40% of accepted claims are genuinely supported by the span they cite.

    TypeScriptReactFastAPIPython
    Read the write-up
  • 09

    Cashflow Risk Intelligence

    Python · FastAPI · PostgreSQL · 3 min read

    13-week
    runway forecast
    Limits: a result published with its documented limitsRUN LOG
    run log
    Screenshot of the Cashflow Risk Intelligence live demo

    Which of a UK small business's unpaid invoices could break its cash runway, when the risk appears, and what to do this week: from an invoice CSV it forecasts a 13-week runway, ranks invoices by expected cash at risk with a plain-English reason on every score, enriches customer risk with Companies House filings, and writes the week's action brief — behind tested multi-tenant RBAC, a STRIDE threat model, and a DPIA.

    PythonFastAPIPostgreSQLNext.js
    Read the write-up
  • 10

    Marketing Effectiveness Lab

    Python · pandas · NumPy · 2 min read

    no metric published
    ARCHIVED
    rosscyking1115.github.io
    Screenshot of the Marketing Effectiveness Lab live demo

    Helps a UK ecommerce team decide where next quarter's marketing budget actually drives incremental revenue — turning noisy multi-channel data into cautious, uncertainty-aware budget recommendations via marketing-mix modelling, a Bayesian posterior layer, lift-test calibration, and a constrained budget optimiser, with a Streamlit executive dashboard.

    PythonpandasNumPystatsmodels
    Read the write-up